llms.txt, robots.txt and AI Crawlers: A 30-Minute Setup Checklist
Three plain files decide what AI crawlers can read on your site. Here is the 30-minute setup, checked on November 11, 2026 against what OpenAI, Anthropic, Google and Perplexity say on their own pages.
- Numbers in the post
- Crawlers in the post and what it says to do with each
- The post’s robots.txt file
Three plain files decide what AI crawlers can read on your site. Here is the 30-minute setup, checked on November 11, 2026 against what OpenAI, Anthropic, Google and Perplexity say on their own pages.
Where the data comes from: the checklist’s own November 11, 2026 reread of the crawler pages of OpenAI, Anthropic, Google and Perplexity, and the sources named in each row.
- Medium post: llms.txt, robots.txt and AI Crawlers: A 30-Minute Setup Checklist
- RankControl, an AI SEO and AEO platform
- Google Doc: How to Check Which AI Crawlers Visit Your Website
- Google Sites page: Which AI Bots Cloudflare Counted, and What Sites Blocked
Numbers in the post
| Number | What the post says | Source | Date |
|---|---|---|---|
| 305% | “Cloudflare’s July 2025 crawler report counted GPTBot requests up 305% between May 2024 and May 2025” | Cloudflare, “From Googlebot to GPTBot: who’s crawling your site in 2025” | May 2024 to May 2025 (report of July 2025) |
| 80% / 18% / 2% | “Cloudflare’s August 29, 2025 (last 12 months) breakdown of AI crawling said 80% was for training and 18% search and 2% user actions” | Cloudflare, “The crawl-to-click gap” | August 29, 2025 (last 12 months) |
| 44.2% of 18,012 | “in Kevin Indig’s Growth Memo analysis of 18,012 ChatGPT citations, published February 16, 2026, 44.2% came from the first 30% of the text” | Kevin Indig, Growth Memo | February 16, 2026 |
| nearly 300,000 | “SE Ranking even looked at nearly 300,000 domains and found no correlation (measurably) between having it and being cited more” | SE Ranking | Page dated September 2026 |
| 0 of 4 | “Neither Anthropic nor Google mention it at all. And OpenAI and Perplexity only mention it to refer readers to their respective documentation index. So none of the 4 claim their crawlers read the file.” | Search Shift check of the crawler pages of OpenAI, Anthropic, Google and Perplexity | November 11, 2026 |
| about 24 hours | “OpenAI says that it can take about 24 hours for robots.txt changes to propagate to their search functionality” | OpenAI crawler page | Checked November 11, 2026 (page undated) |
| 200 | “Its robots.txt returned 200 and holds an Allow: / group for GPTBot, ClaudeBot and PerplexityBot. The homepage returned 200 to a GPTBot user-agent string, a ClaudeBot one and a plain browser one, and rctrl.com/llms.txt returned 200.” | Search Shift check of rctrl.com | November 11, 2026 |
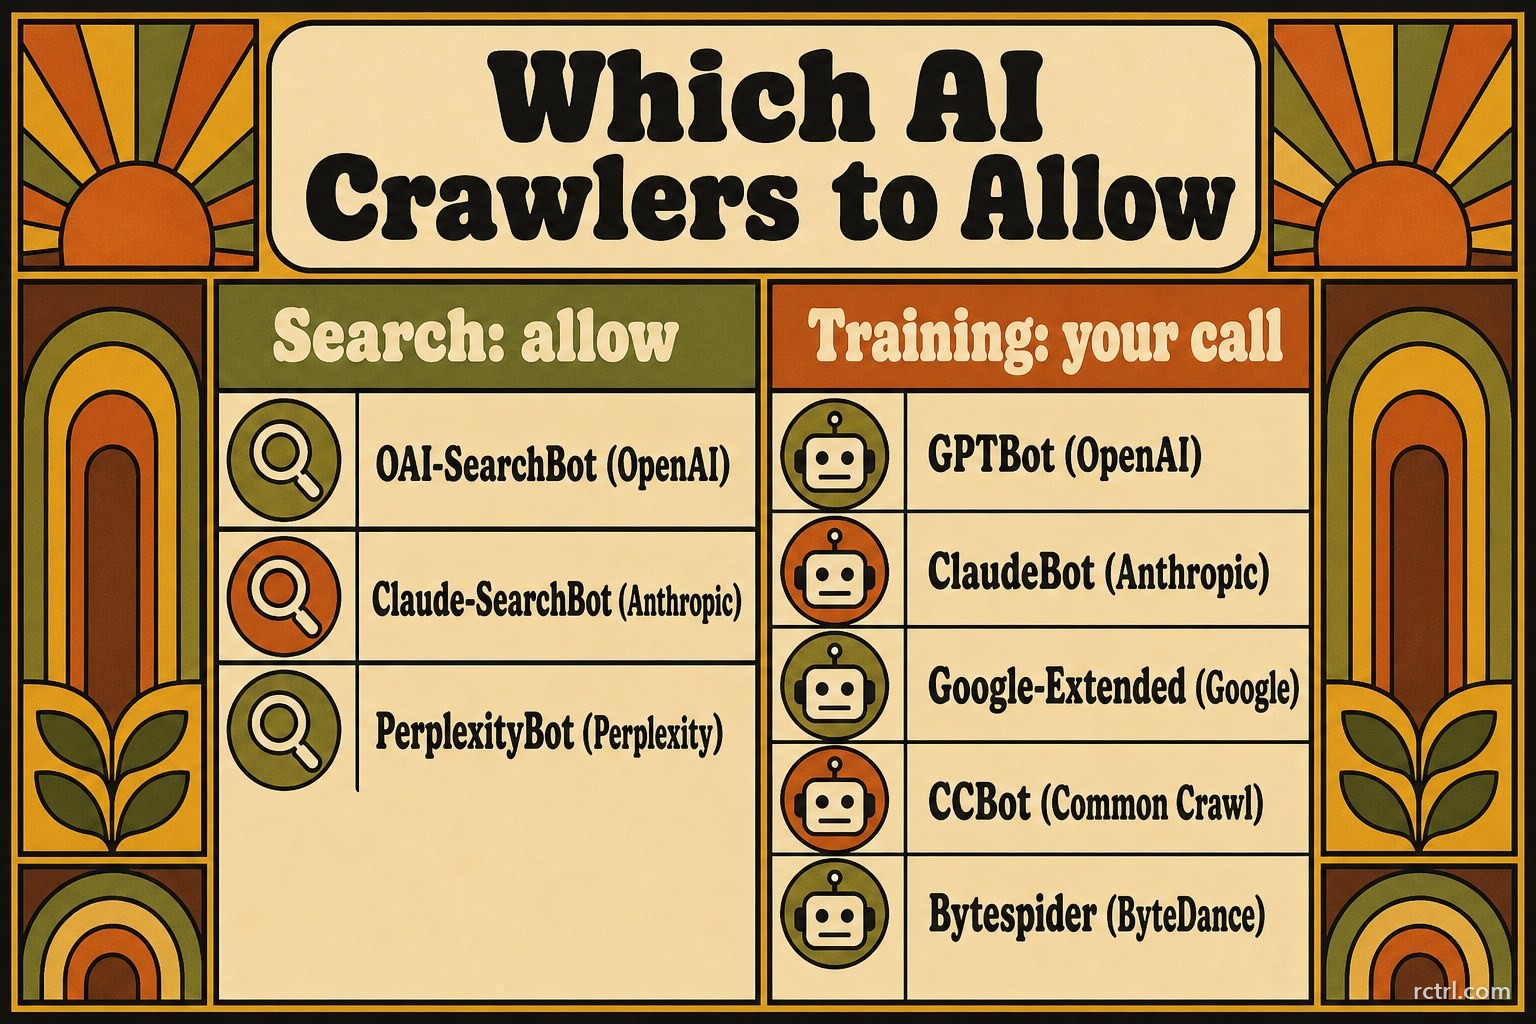
Crawlers in the post and what it says to do with each
| Crawler | Company | What the post says it does | What the post says to do | Source, date |
|---|---|---|---|---|
| OAI-SearchBot | OpenAI | “fetch pages so an AI product can show them in answers”; “sites opted out of OAI-SearchBot will not be shown in ChatGPT search answers” | Allow. “First three are search crawler friendly.” “block OAI-SearchBot to keep your pages from being in its answers” | OpenAI crawler page, November 11, 2026 |
| Claude-SearchBot | Anthropic | “fetch pages so an AI product can show them in answers” | Allow. “First three are search crawler friendly.” | Anthropic crawler page, November 11, 2026 |
| PerplexityBot | Perplexity | “PerplexityBot is not used to train foundation models” | Allow. “First three are search crawler friendly.” | Perplexity crawler page, November 11, 2026 |
| GPTBot | OpenAI | “OpenAI docs GPTBot as the training crawler in 2026”; “if you block GPTBot/ClaudeBot, it’s off limits for training” | Disallow. “Last five are opting out of training.” “Block GPTBot and ChatGPT search can still be used” | OpenAI crawler page, November 11, 2026 |
| ClaudeBot | Anthropic | “if you block GPTBot/ClaudeBot, it’s off limits for training” | Disallow. “Last five are opting out of training.” | Anthropic crawler page, November 11, 2026 |
| Google-Extended | “a robots.txt token that does not have a user-agent string”; “used to control the training for future models of Gemini and also the grounding part”; “doesn’t impact Google Search” | Disallow. “Definitely take a second look at Google-Extended before blocking because Google puts Gemini Apps grounding alongside training in what the token controls.” | Google crawler page, November 11, 2026 | |
| CCBot | Common Crawl | “CCBot (open training data of Common Crawl)” | Disallow. “Last five are opting out of training.” | The post’s list (no source page named) |
| Bytespider | ByteDance | “Bytespider (ByteDance for TikTok/Doubao)”; “Bytespider respects robots.txt not always” | Disallow. “Last five are opting out of training.” | The post’s list (no source page named) |
| GoogleOther | “generic crawler for one-off research crawls etc., rules for it don’t impact any specific product” | Not in the post’s file. “Then check Googlebot (not GoogleOther).” | Google crawler page, November 11, 2026 | |
| Googlebot | “AI is incorporated into Search”; “So Googlebot robots.txt is the key” | “Then check Googlebot (not GoogleOther).” | Google AI features page, November 11, 2026 | |
| ChatGPT-User | OpenAI | “pulling one page as a result of being asked by a human”; “OpenAI’s crawler page makes it sound like they might ignore robots.txt stuff for ChatGPT-User” | Not in the post’s file | OpenAI crawler page, November 11, 2026 |
| Claude-User | Anthropic | “pulling one page as a result of being asked by a human”; “If you turn off Claude-User, Anthropic claims that will prevent them pulling your stuff for the user’s question” | Not in the post’s file | Anthropic crawler page, November 11, 2026 |
| Perplexity-User | Perplexity | “pulling one page as a result of being asked by a human”; “Perplexity claims they generally don’t respect robots.txt stuff for Perplexity-User” | Not in the post’s file | Perplexity crawler page, November 11, 2026 |
The post’s robots.txt file
# Allow AI search crawlers
User-agent: OAI-SearchBot
Allow: /

User-agent: Claude-SearchBot
Allow: /

User-agent: PerplexityBot
Allow: /

# Opt out of model training
User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: Google-Extended
Disallow: /

User-agent: CCBot
Disallow: /

User-agent: Bytespider
Disallow: /
- Reference: https://medium.com/@thesearchshift/llms-txt-robots-txt-and-ai-crawlers-a-30-minute-setup-checklist-7c6164565dec
- Reference: https://rctrl.com
- Reference: https://docs.google.com/document/d/1MdIK63_iiakeenDLC00acP2aeioWpHI-wNLpX5xzuMk/edit?usp=sharing
- Reference: https://sites.google.com/view/search-shift-notes/ai-crawler-counts-cloudflare
- Reference: https://rankcontrol.github.io/images/native-016-llms-txt-robots-txt-ai-crawlers-2026-checklist-info-crawlers-wm.jpg
- Reference: https://blog.cloudflare.com/from-googlebot-to-gptbot-whos-crawling-your-site-in-2025/
- Reference: https://blog.cloudflare.com/crawlers-click-ai-bots-training/
- Reference: https://developers.openai.com/api/docs/bots
- Reference: https://developers.openai.com/api/docs/bots
- Reference: https://developers.openai.com/api/docs/bots
- Reference: https://developers.google.com/crawling/docs/crawlers-fetchers/google-common-crawlers
- Reference: https://developers.google.com/crawling/docs/crawlers-fetchers/google-common-crawlers
- Reference: https://developers.google.com/search/docs/appearance/ai-features
- Reference: https://developers.openai.com/api/docs/bots
Write a comment