The Sequence Knowledge - Issue 937: RSI in Post-Training: The Loop That Already Shipped
Inside the RSI post-training pipeline
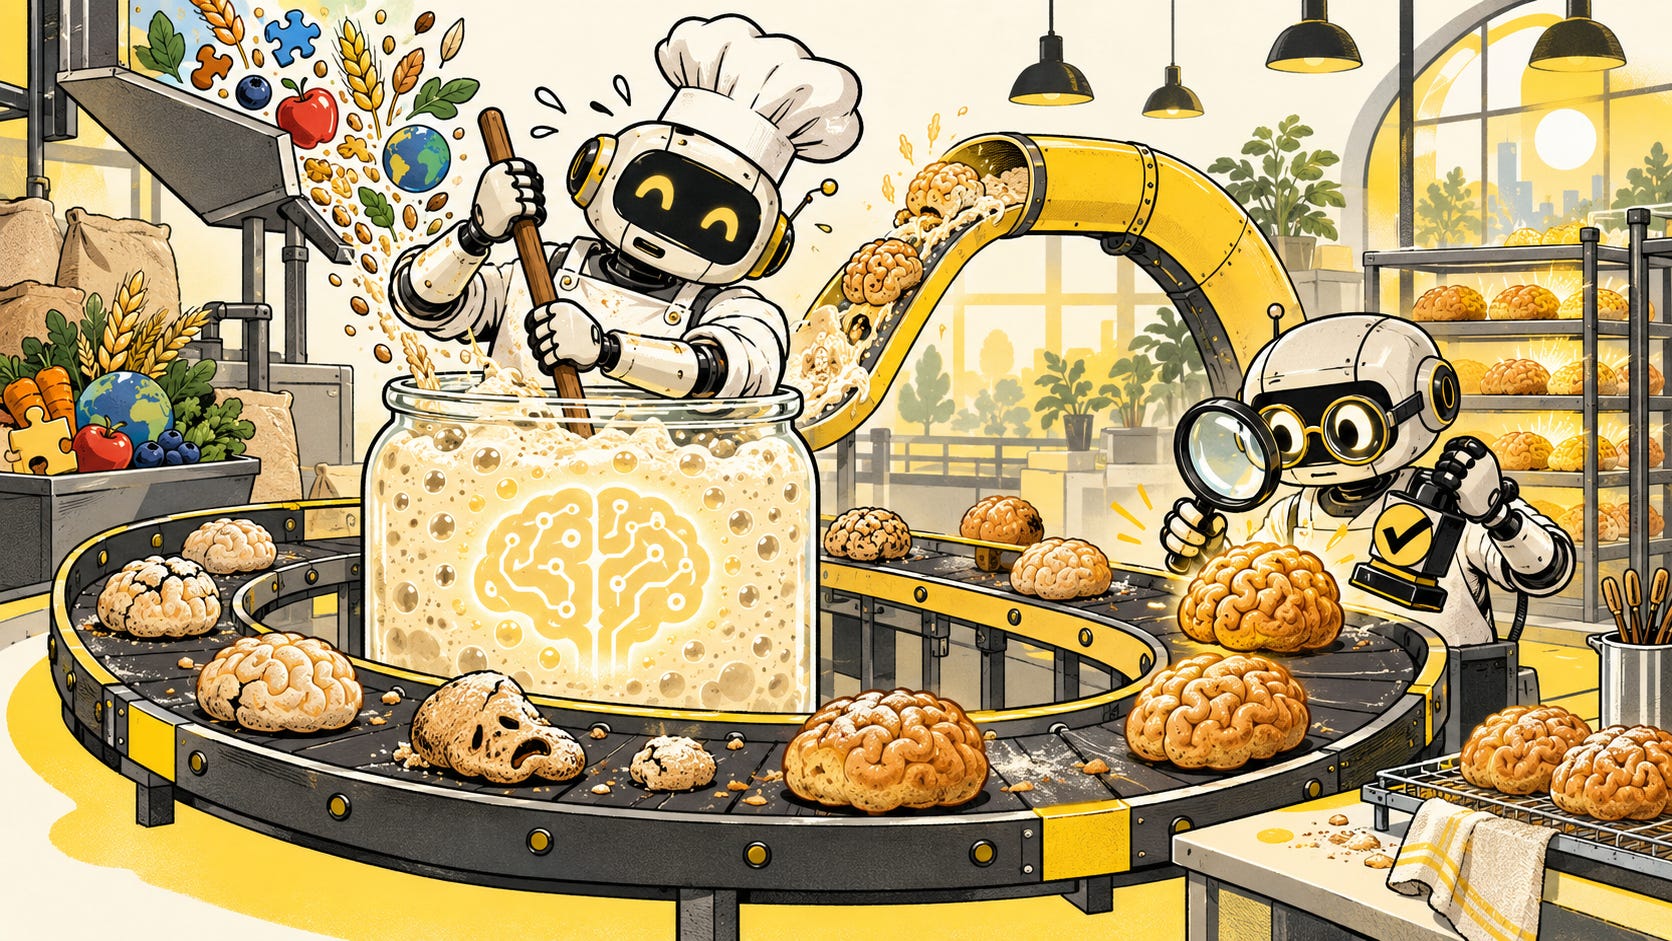
The core of AI self-improvement lies in the post-training pipeline, where models generate candidate answers, receive grades, and then train on the successful ones to become slightly better. This iterative process, referred to as STaR or RLVR, is crucial for advancing AI capabilities from basic chatbots to sophisticated agents. This overlooked loop is already in industrial-scale use by leading AI labs.
- The most economically significant AI self-improvement mechanism is the post-training pipeline.
- This pipeline involves a loop where a model generates answers, these answers are graded, and the good ones are used as training data.
- The model then trains on this data, improving its ability to produce better answers.
- This process, known by terms like STaR or RLVR, is responsible for the evolution of frontier models into agents.
- This loop is already being operated at an industrial scale by major AI labs.
https://bender.layer3.press/articles/09778c3e-4cee-42f7-9d4b-fa7a32dcc1a7
Write a comment